Audio Generation node
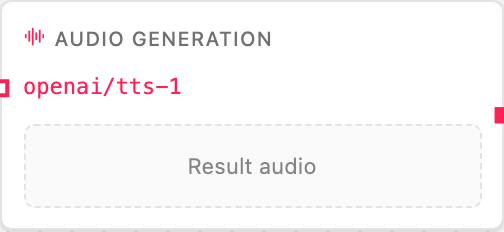
The Audio Generation node synthesizes speech audio from text (text-to-speech) using a speech model.
Handles
| Handle | Purpose |
|---|---|
prompt | The text to speak (required) |
Configuration
- Model — the speech model (e.g.
openai/tts-1). - Voice — the voice to use.
- Output format — audio format (e.g.
mp3). - Instructions — extra style guidance.
- Speed — playback speed.
- Language — the spoken language, when the model has such a lever.
Not every model honors every field. Fish Audio, for example, infers the language from the text and the chosen voice and has no language parameter at all — so for German audio the upstream Prompt or Agent node has to produce German text. Whenever a provider drops a setting, the run panel lists it under Ignored settings and the node card shows an “ignored” chip; the run itself still succeeds.
Example
Prompt node → Audio Generation:
prompt: "Welcome to Sobmit — the visual workflow builder for AI agents."
model: openai/tts-1
The generated audio ({ dataUrl, mime }) becomes the payload, rendered as an
inline player on the card.
Notes
- The text is required — the engine fails fast without it.
- The card shows an inline
<audio>player and artifact history.
Related
- Transcribe Audio — the reverse direction.